Service Details
We build and operate closed, on-premises LLM / RAG platforms and infrastructure automation for small and mid-sized businesses.
Generative AI that runs only inside your company
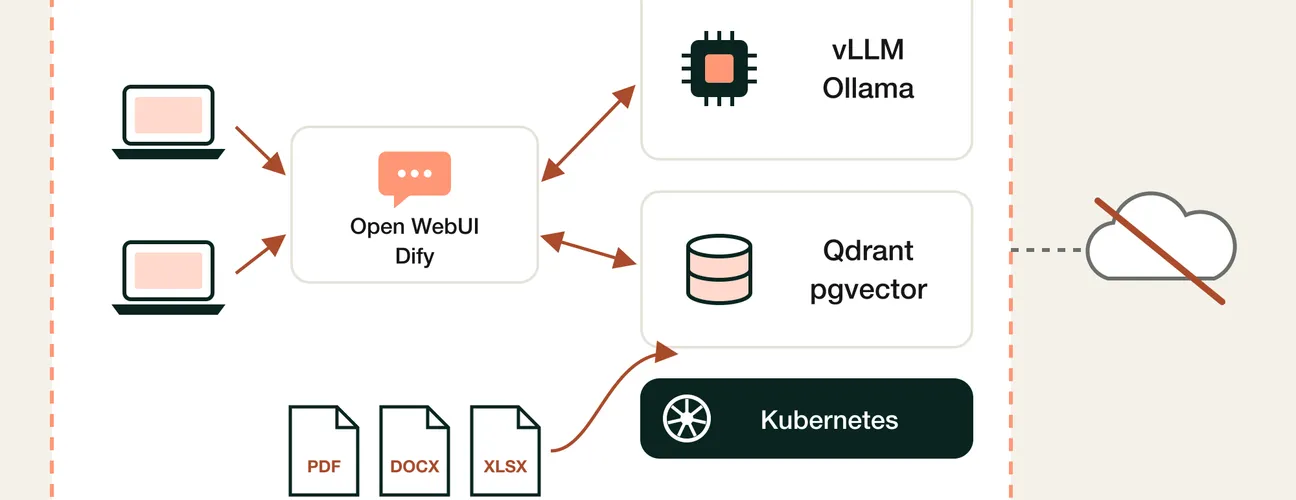
We build an environment where you can search, summarize and draft with generative AI without sending your documents or data to an external cloud. The servers sit in your office or data center, and can run fully disconnected from the internet.
Sound familiar?
- You want to use generative AI, but your rules do not allow internal documents to go to the cloud
- Contracts with partners prohibit drawings or quotes from leaving the company
- There are so many manuals and past documents that finding information takes too long
- You cannot predict how far usage-based cloud costs will grow
- You want to try it, but do not know where to start
Why closed-network and on-premises?
- Data stays inside: ingestion and answer generation both happen in your environment.
- Outbound traffic you can verify: we disable external connections and give you a list of anything that remains.
- Predictable costs: mainly hardware and operations, with no usage-based charges that keep growing.
- Your choice of model: you decide which model and version to use, and when to update.
Sometimes the cloud is the better choice. If your data is not sensitive, usage is light, or you need the latest and most capable models, cloud generative AI is cheaper and easier. We will tell you honestly which fits during the consultation.
What it can do
- Internal document search: find answers in rules, manuals and reports, and show the source documents.
- First-line answers: answer common questions from staff or partners based on your documents.
- Summaries: condense meeting notes and long documents.
- Drafting: draft reports and emails from past materials.
What we provide
- Requirements: users, documents, concurrent users and where the servers will live.
- Hardware selection: GPU servers or workstations that fit your use and team size, with procurement advice. We also check whether existing hardware can be reused.
- Models and inference: models chosen for Japanese performance and commercial-use licenses, served with vLLM or Ollama.
- RAG: ingestion of PDF and Office documents, with search on Qdrant or pgvector.
- User interface: chat and workflow screens with Open WebUI or Dify, chosen after checking their license terms such as user limits and branding.
- Authentication and permissions: Keycloak connected to your accounts, with documents separated by department.
- Logging and monitoring: usage logs, plus monitoring of GPUs and services.
- Operations and handover: we can run the platform, including model updates and patches, and hand over the code and runbooks.
Sizing
We size by concurrent users and document volume, not by headcount.
- Small trial: a workstation with one GPU, to confirm the value with a few users.
- Department: a server with one or two GPUs, with authentication and logging for daily work.
- Company-wide: multiple GPUs managed with Kubernetes (NVIDIA GPU Operator), ready to grow with your users.
How we work
- Free consultation: the work you want to support, the documents and your internal rules.
- Small trial: check answer quality and speed on a subset of your documents.
- Proposal and quote: hardware, architecture, scope and operations.
- Build: from hardware setup to models, RAG, UI, authentication and monitoring.
- Operations: adding documents, updating models and handling incidents.
Timelines depend largely on hardware delivery. We will give you an estimate during the consultation.
Operations and team
Our founding engineer handles everything from design and build to operations. Support hours are weekdays, 9:00–18:00 JST. The setup is kept as code and runbooks so it can be handed over at any time.
FAQ
It depends heavily on your use case and concurrent users, so we quote after a consultation. We also check whether your existing servers or workstations can be used.